AWS architecture for a live product data pipeline, from nightly batch to Kafka Streams
Millions of products, and a data pipeline that processed them once a night, when it didn't fail.
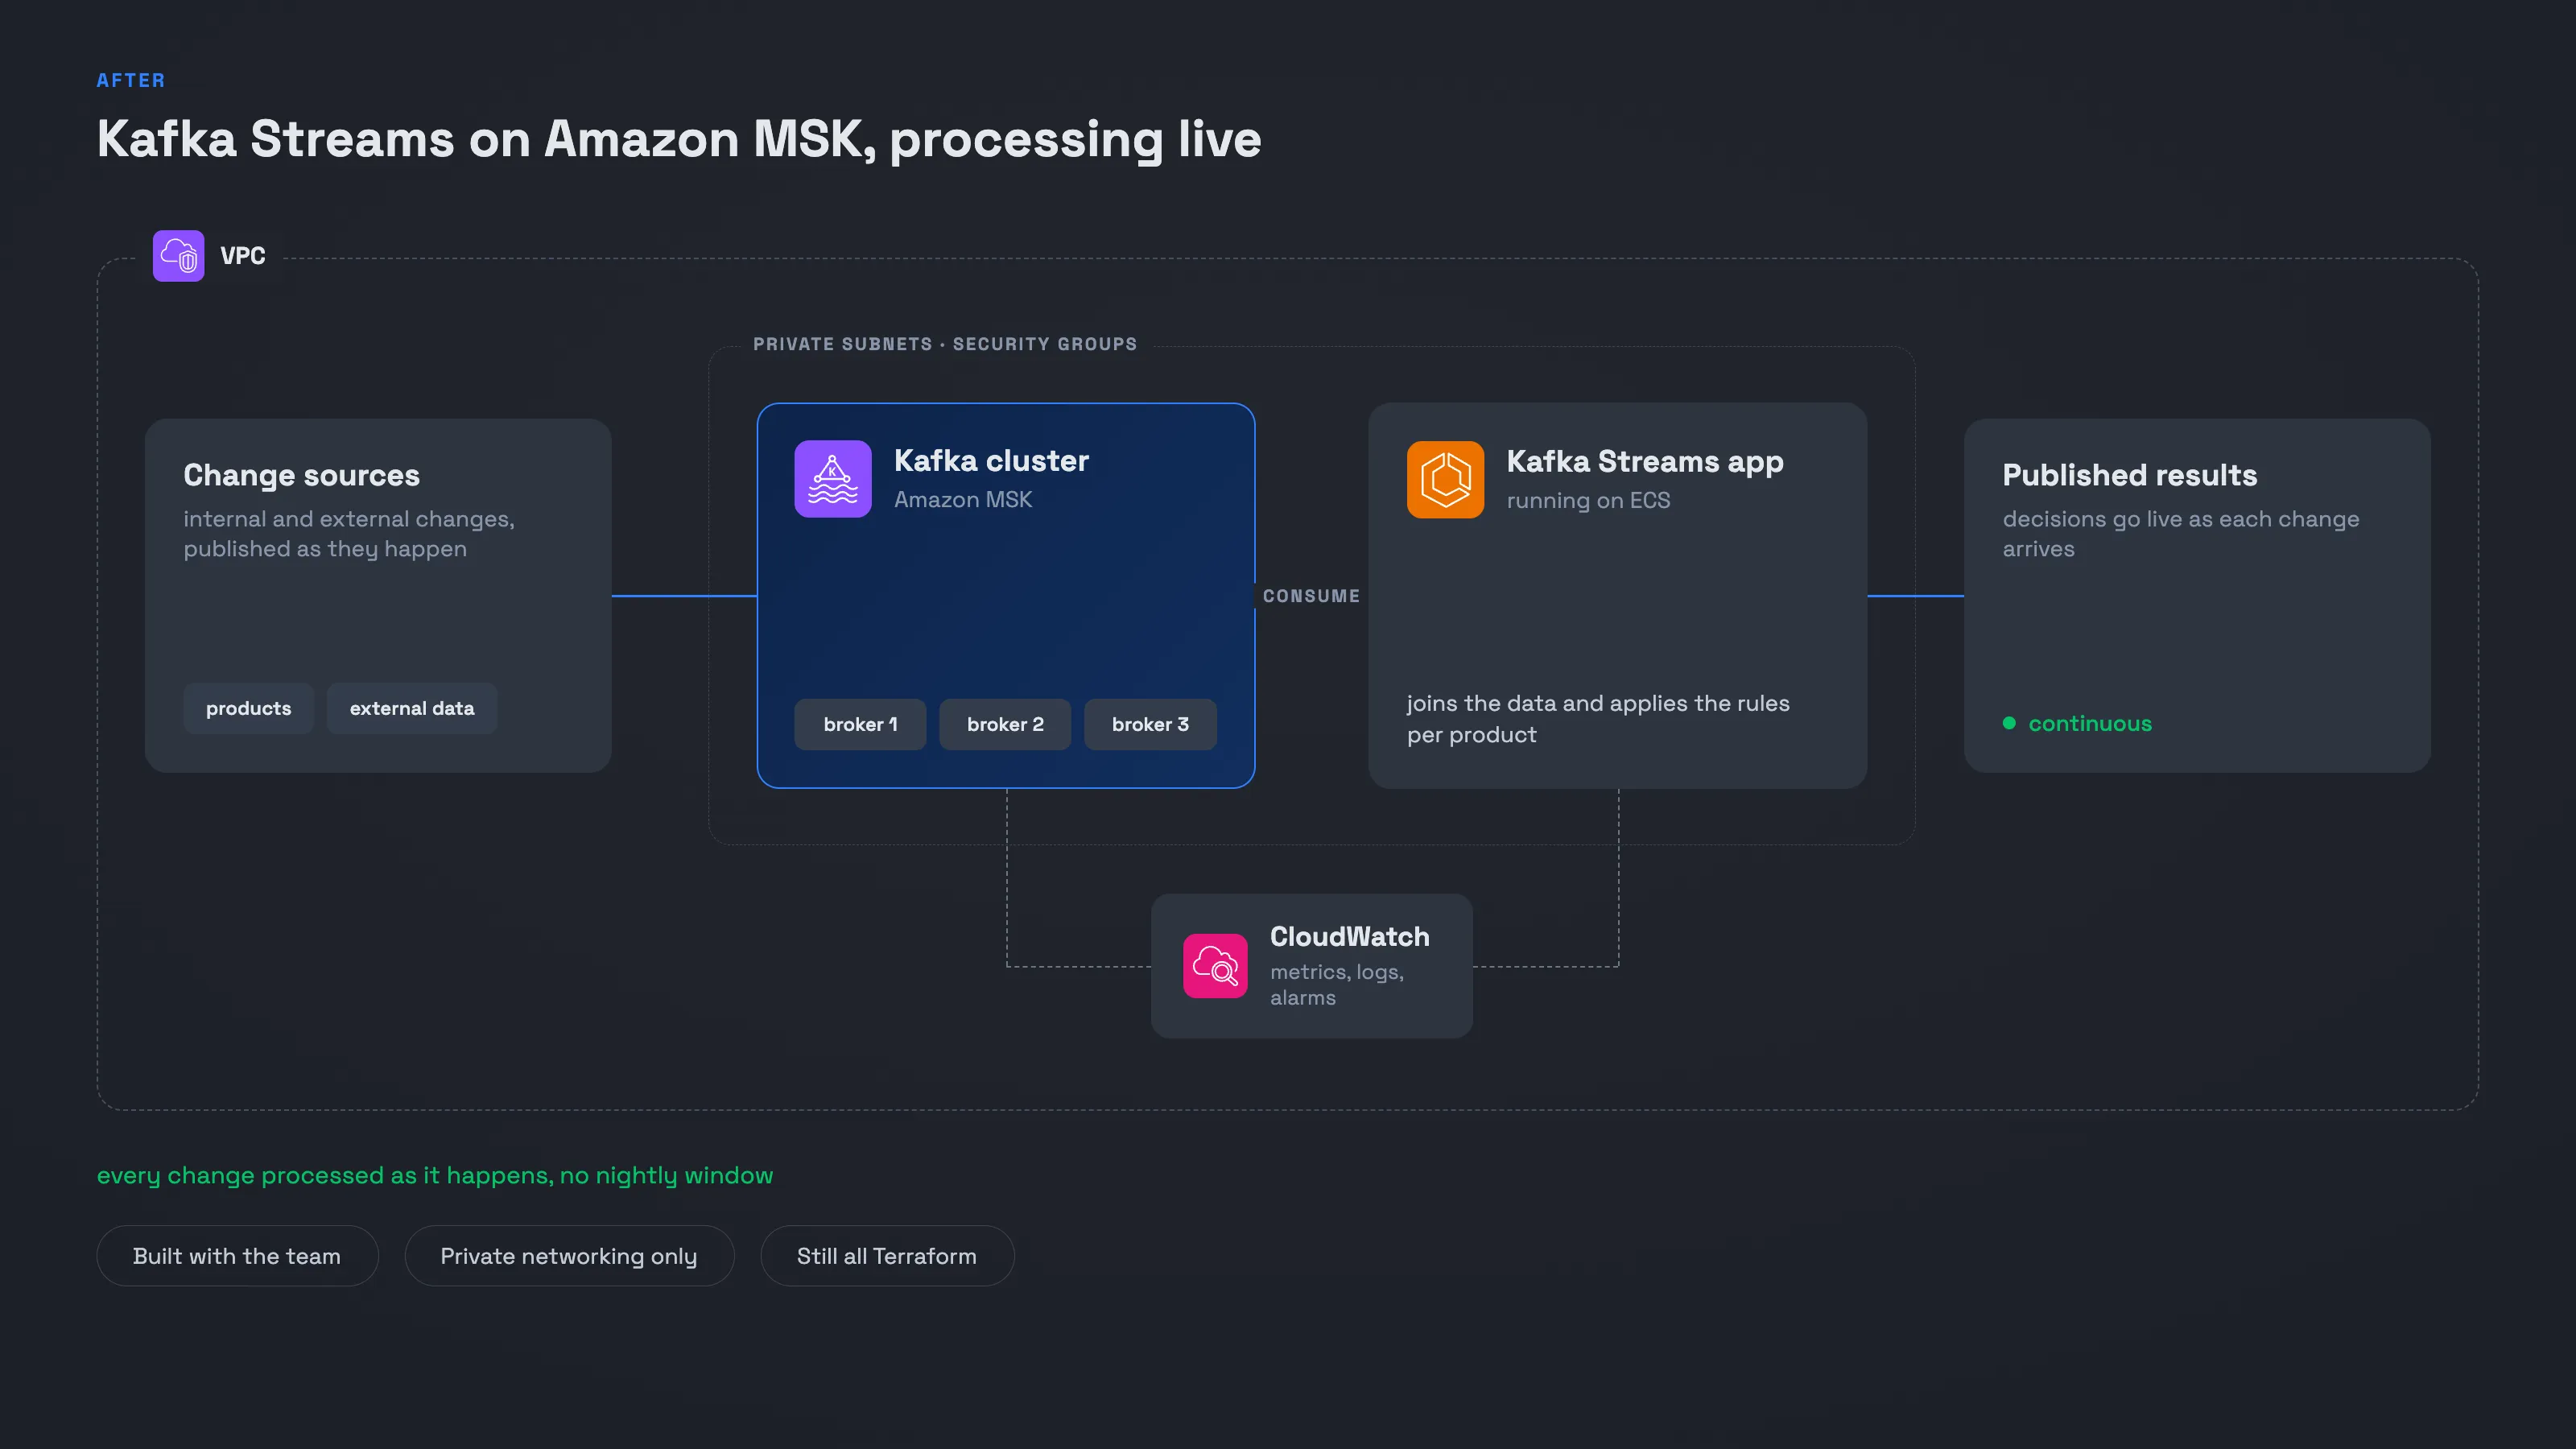
No more failed nightly runs or manual replays. The streaming pipeline processes each change on its own, inside private subnets with scoped security groups.
Decisions are based on current data instead of yesterday's, so results are better and reach customers sooner.
The story
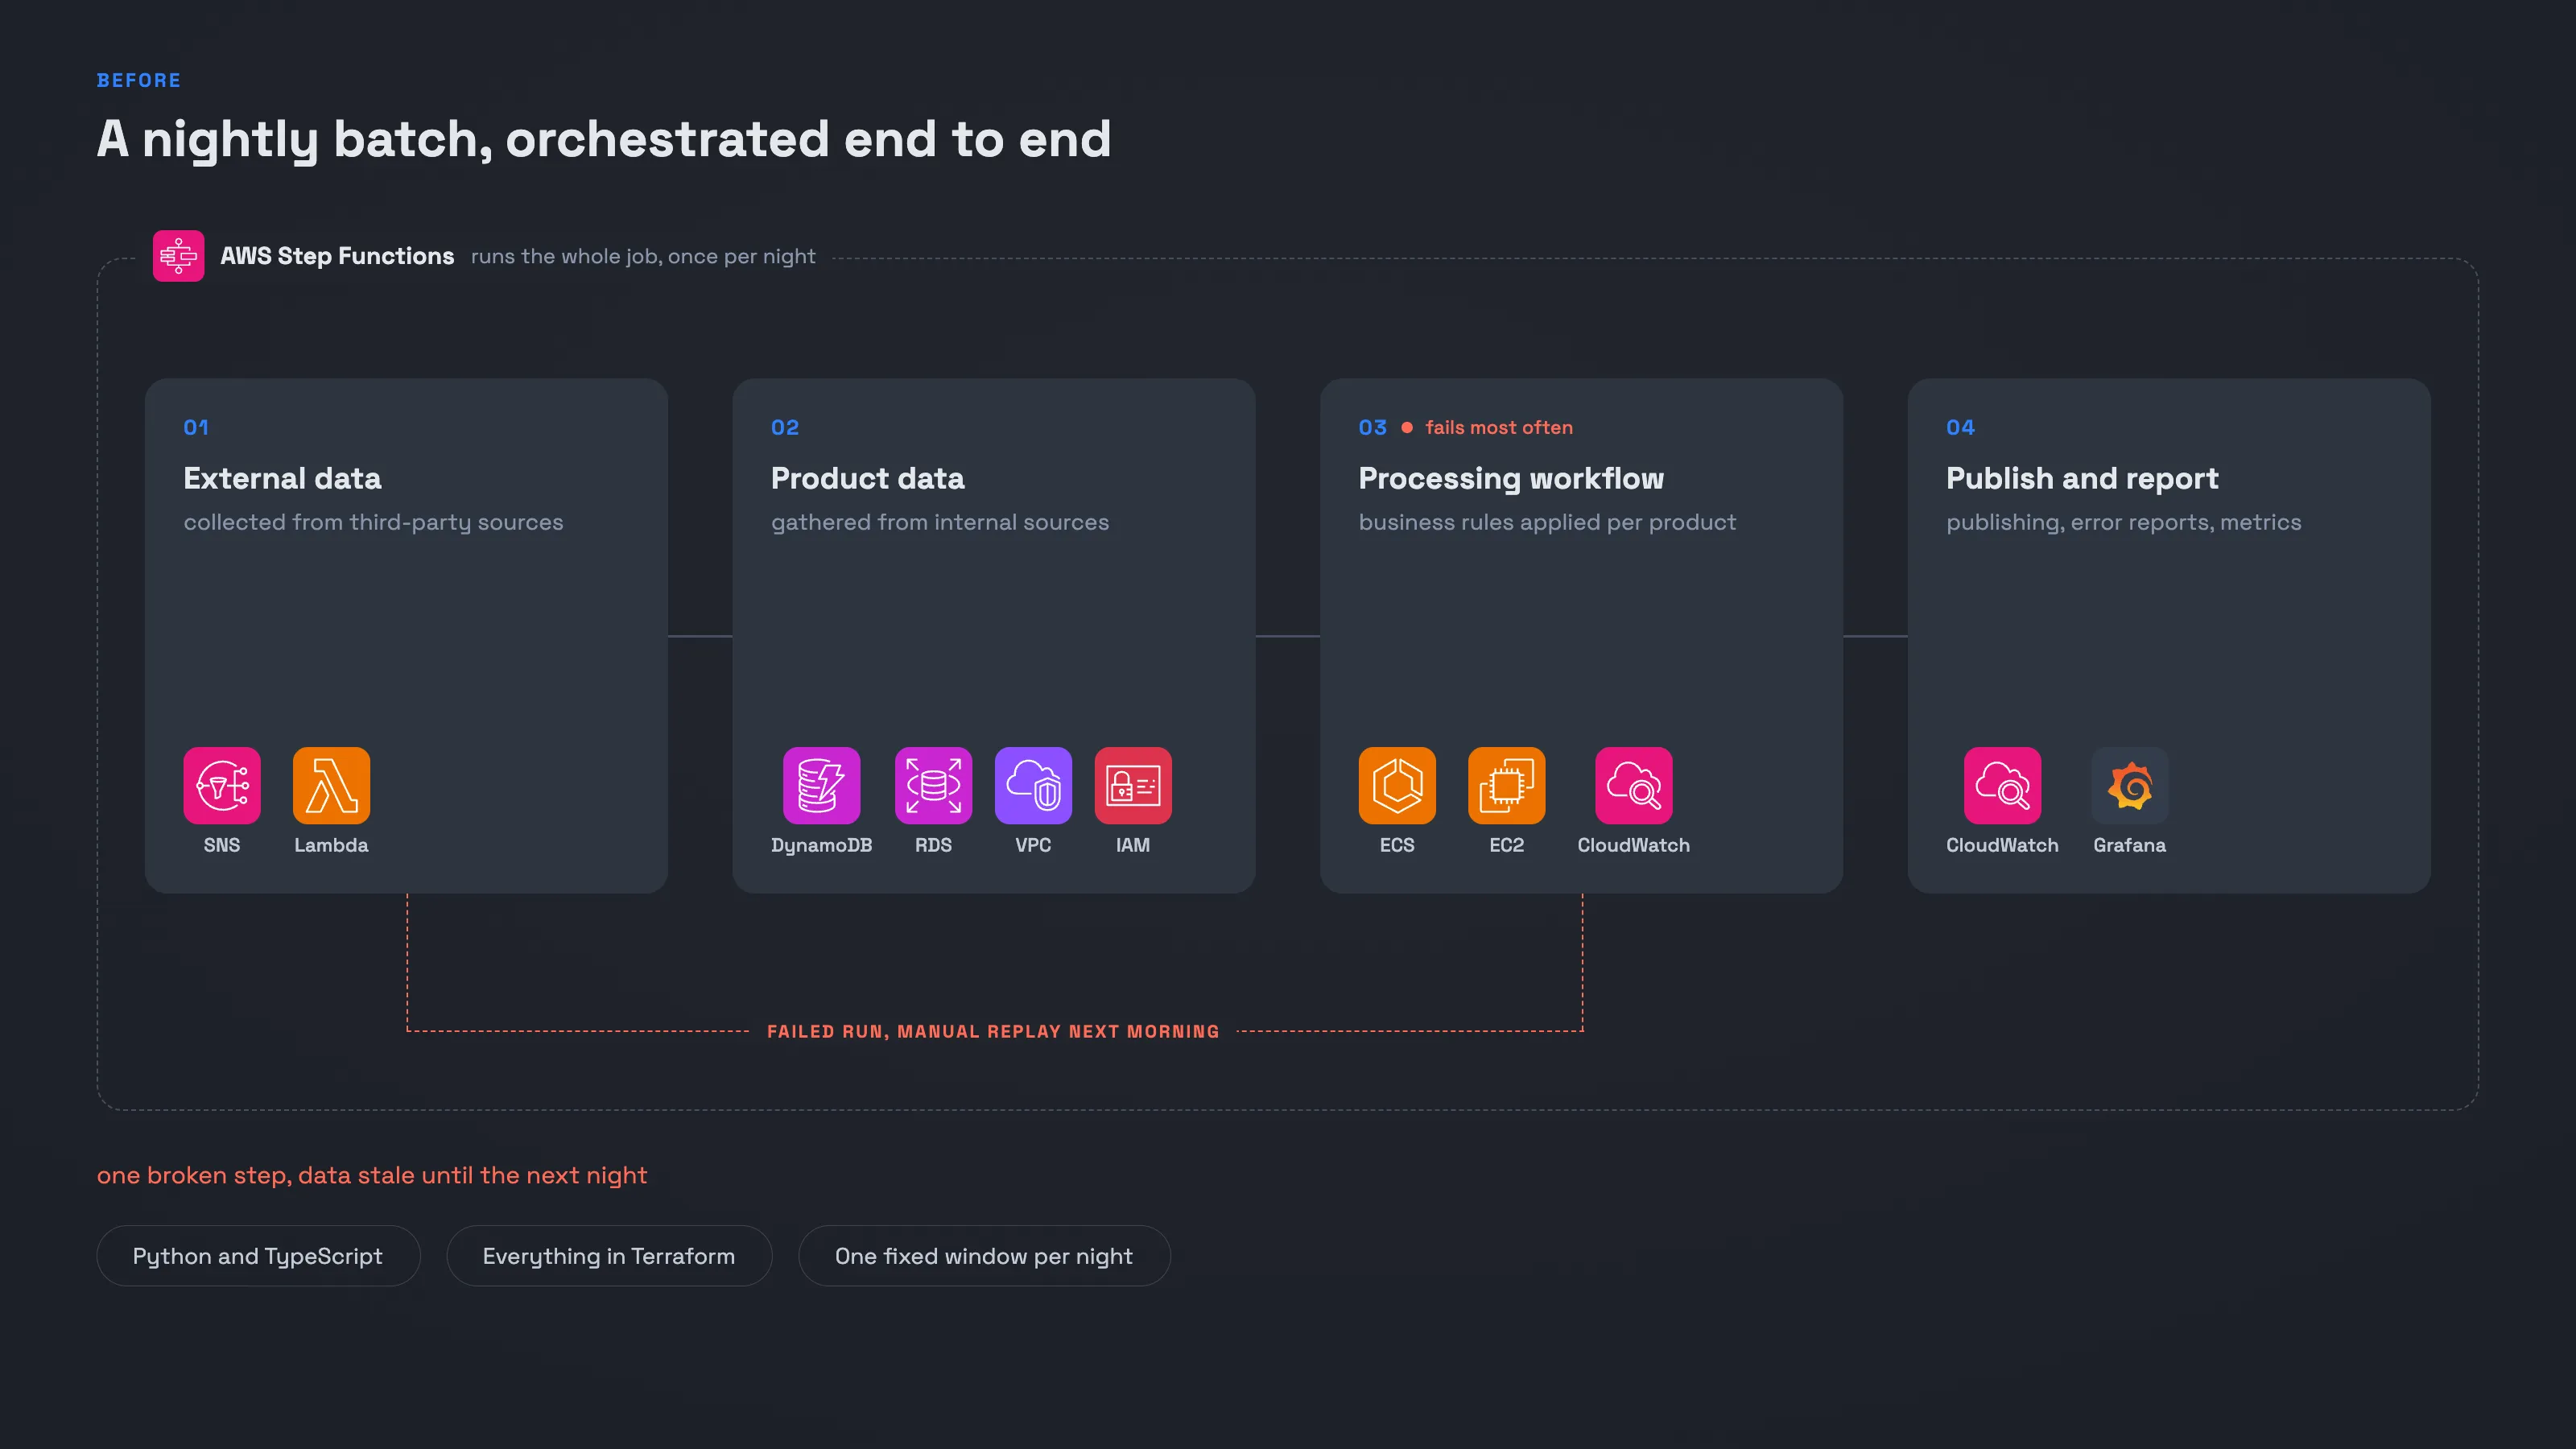
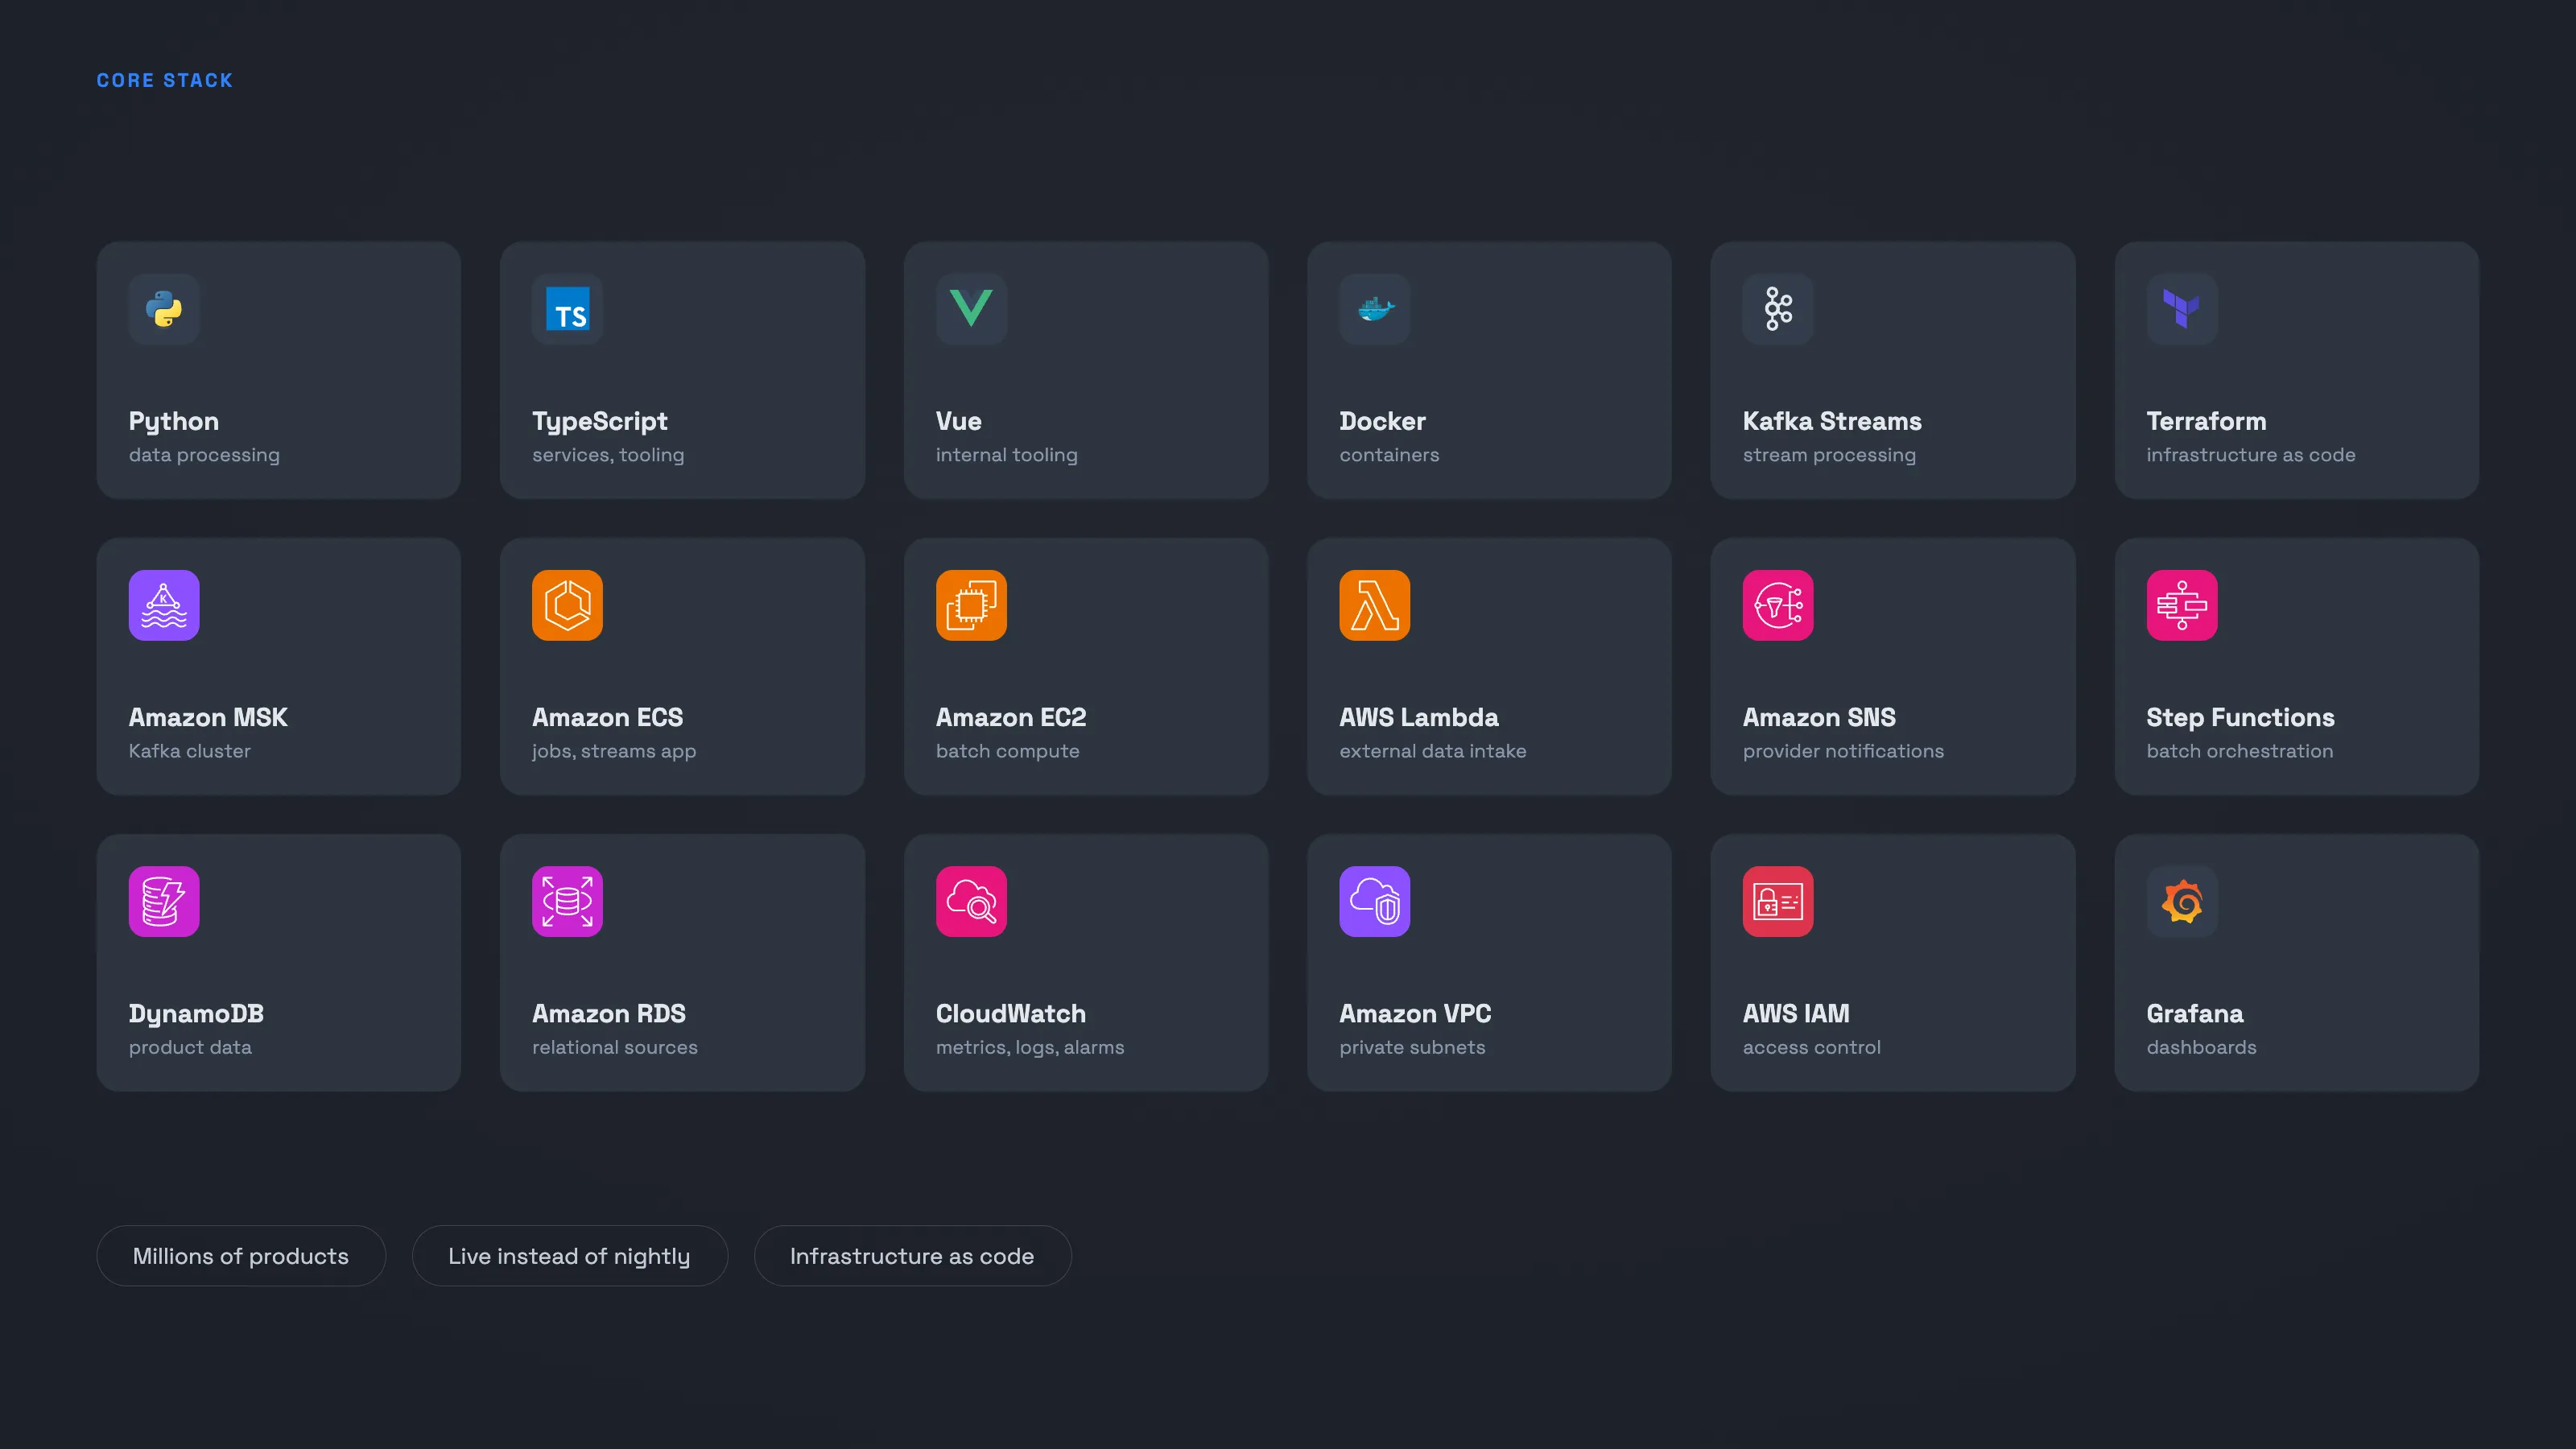
Every product in the catalogue needs to be processed and published based on business rules. For millions of products that ran as a nightly batch job. Step Functions orchestrated SNS, Lambdas, ECS jobs, EC2 and DynamoDB, written in Python and TypeScript and provisioned with Terraform.
I maintained that pipeline, and it failed often. It was a long chain of steps in one fixed window, so one broken step left the data stale until the next night.
With the team I rebuilt it as a Kafka Streams application on Amazon MSK, running on ECS inside private subnets. Changes now flow through Kafka and are processed as they happen, instead of once a night.
Technology


Other case studies worth a look
Working on something similar?
Tell me what you run today and where it hurts. I will come back with how I would build it, and what I would leave alone.
Discuss your project