MLOps on AWS: training and serving a product classification model
A large online retailer, a catalogue of millions of products, and a model that turns raw product data into consistent, structured information.
Consistently classified products are easier to find in search and navigation.
Products that are found more often are products that sell more often.
The story
On a catalogue with millions of products, product data arrives incomplete and inconsistent. Doing classification by hand does not scale, so the goal was a trained model that does it automatically, based on different kinds of product data.
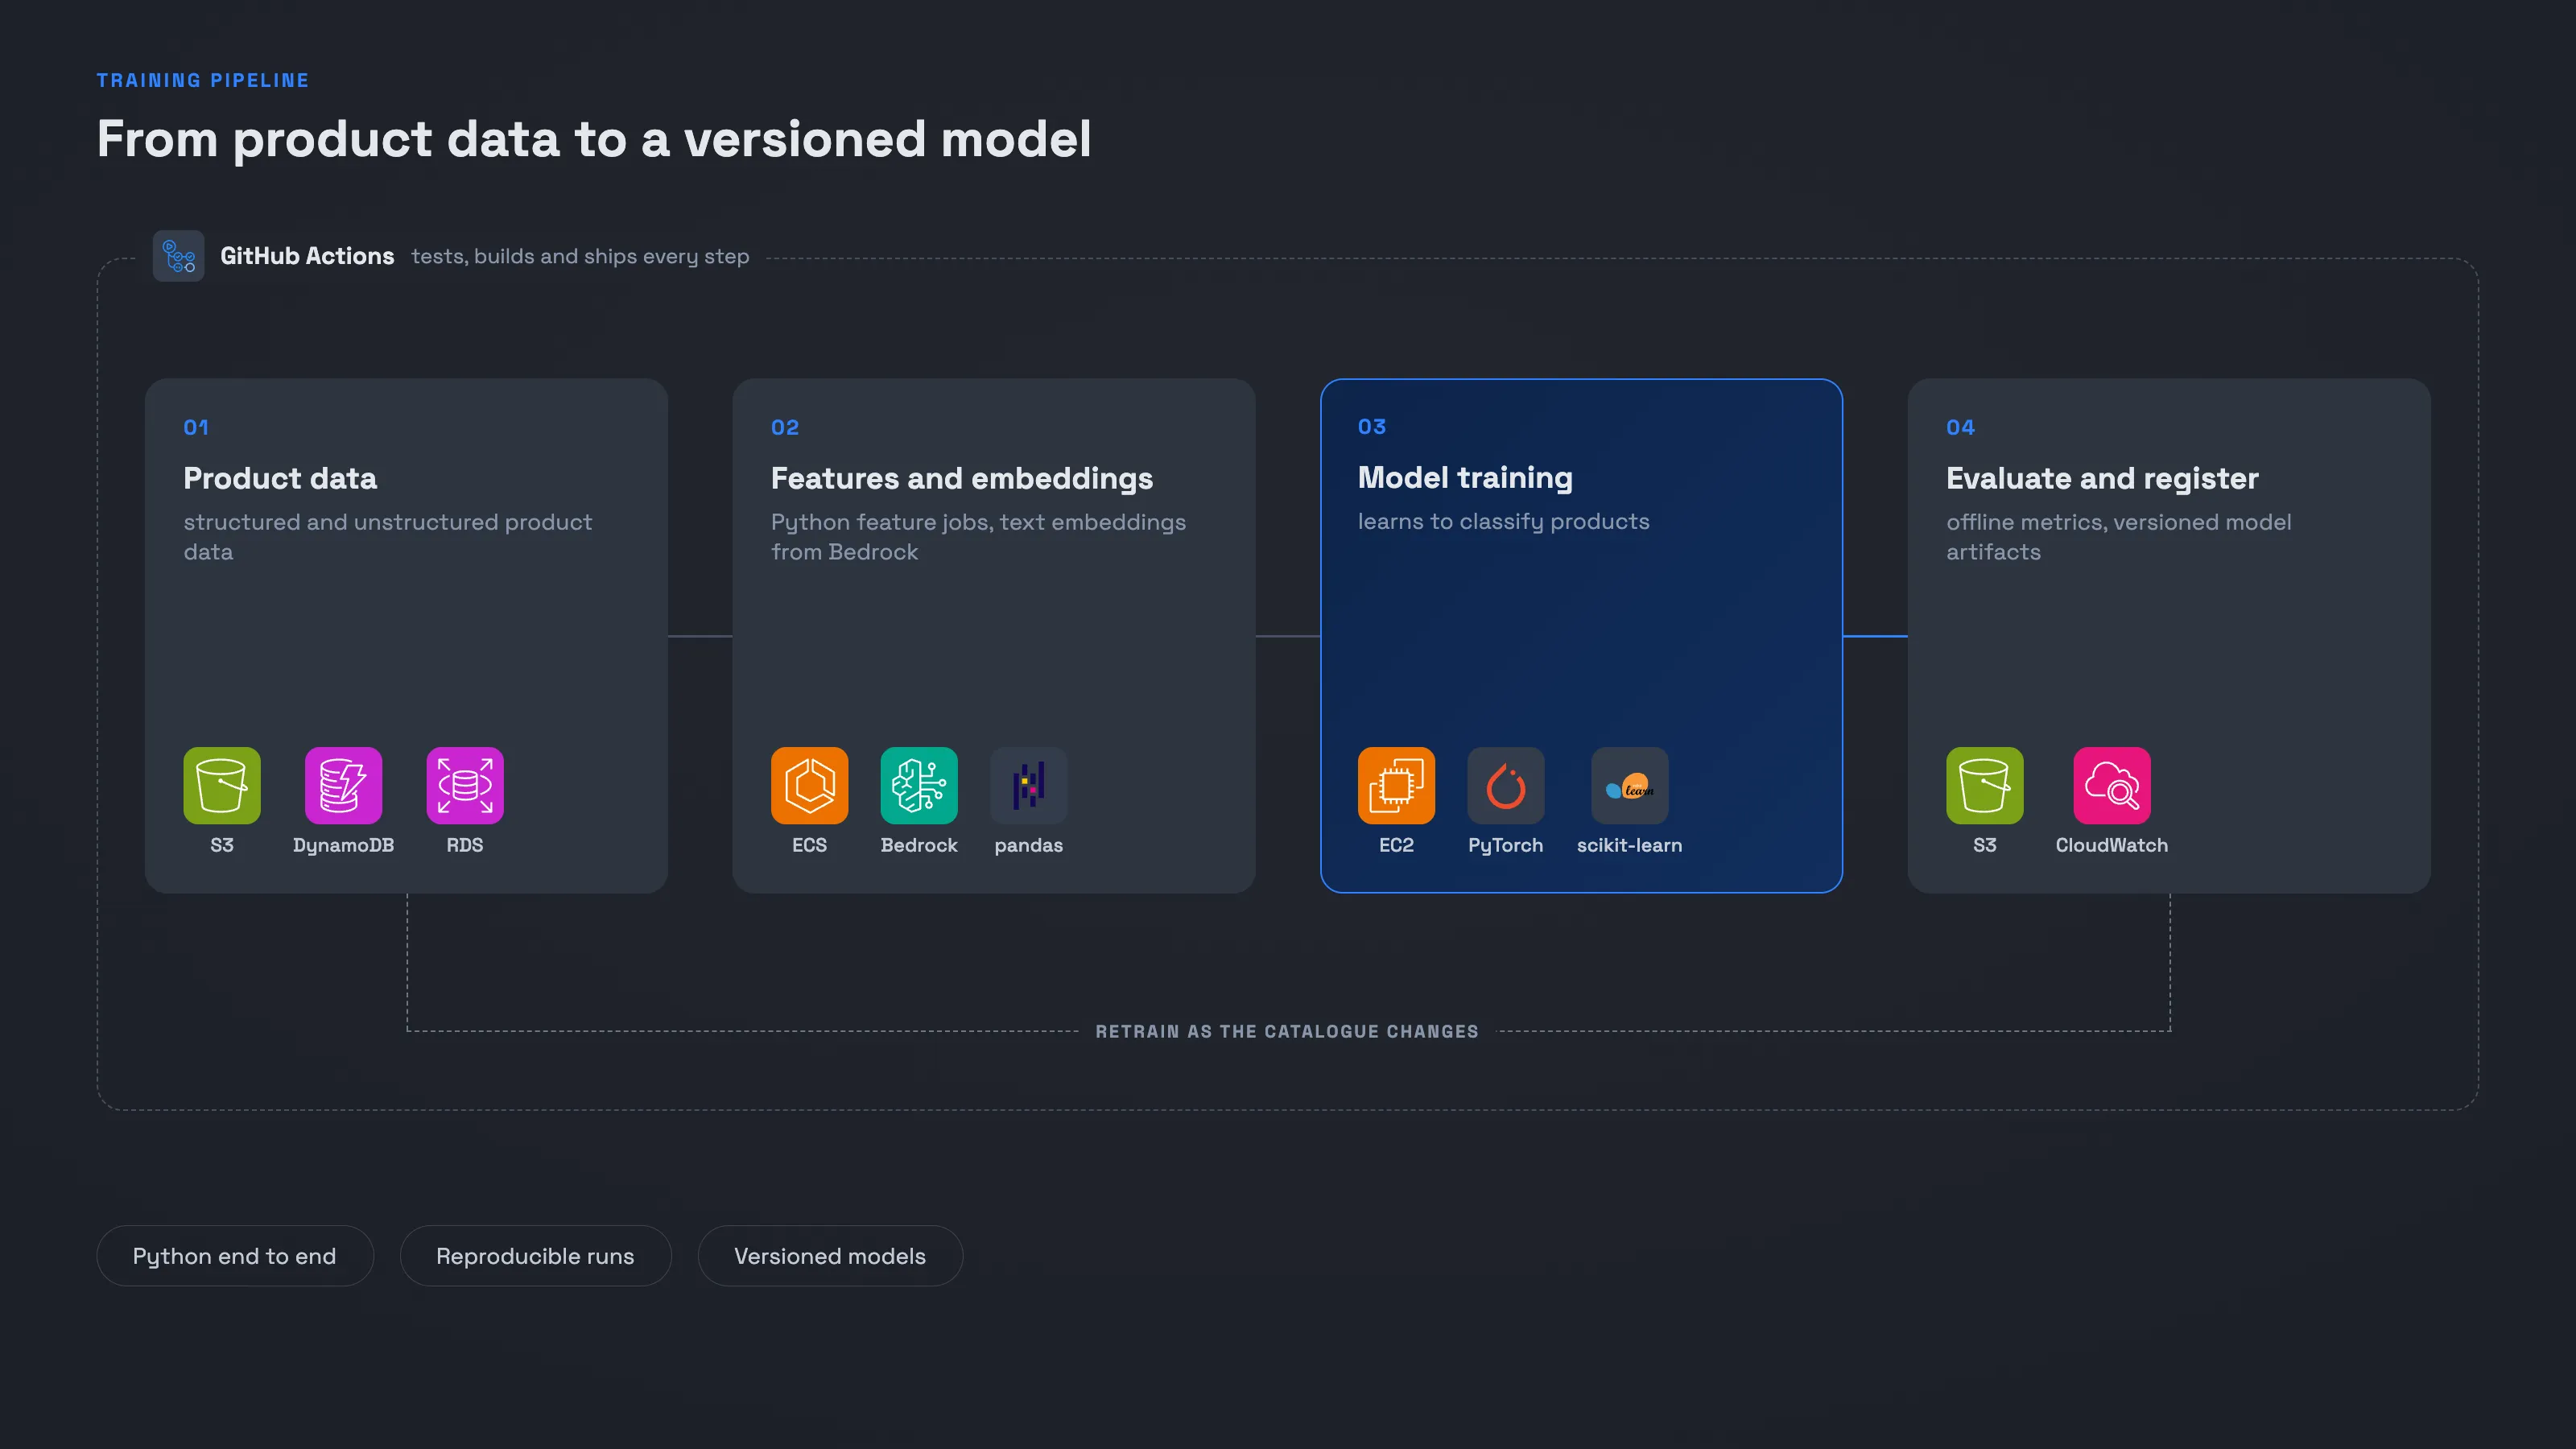
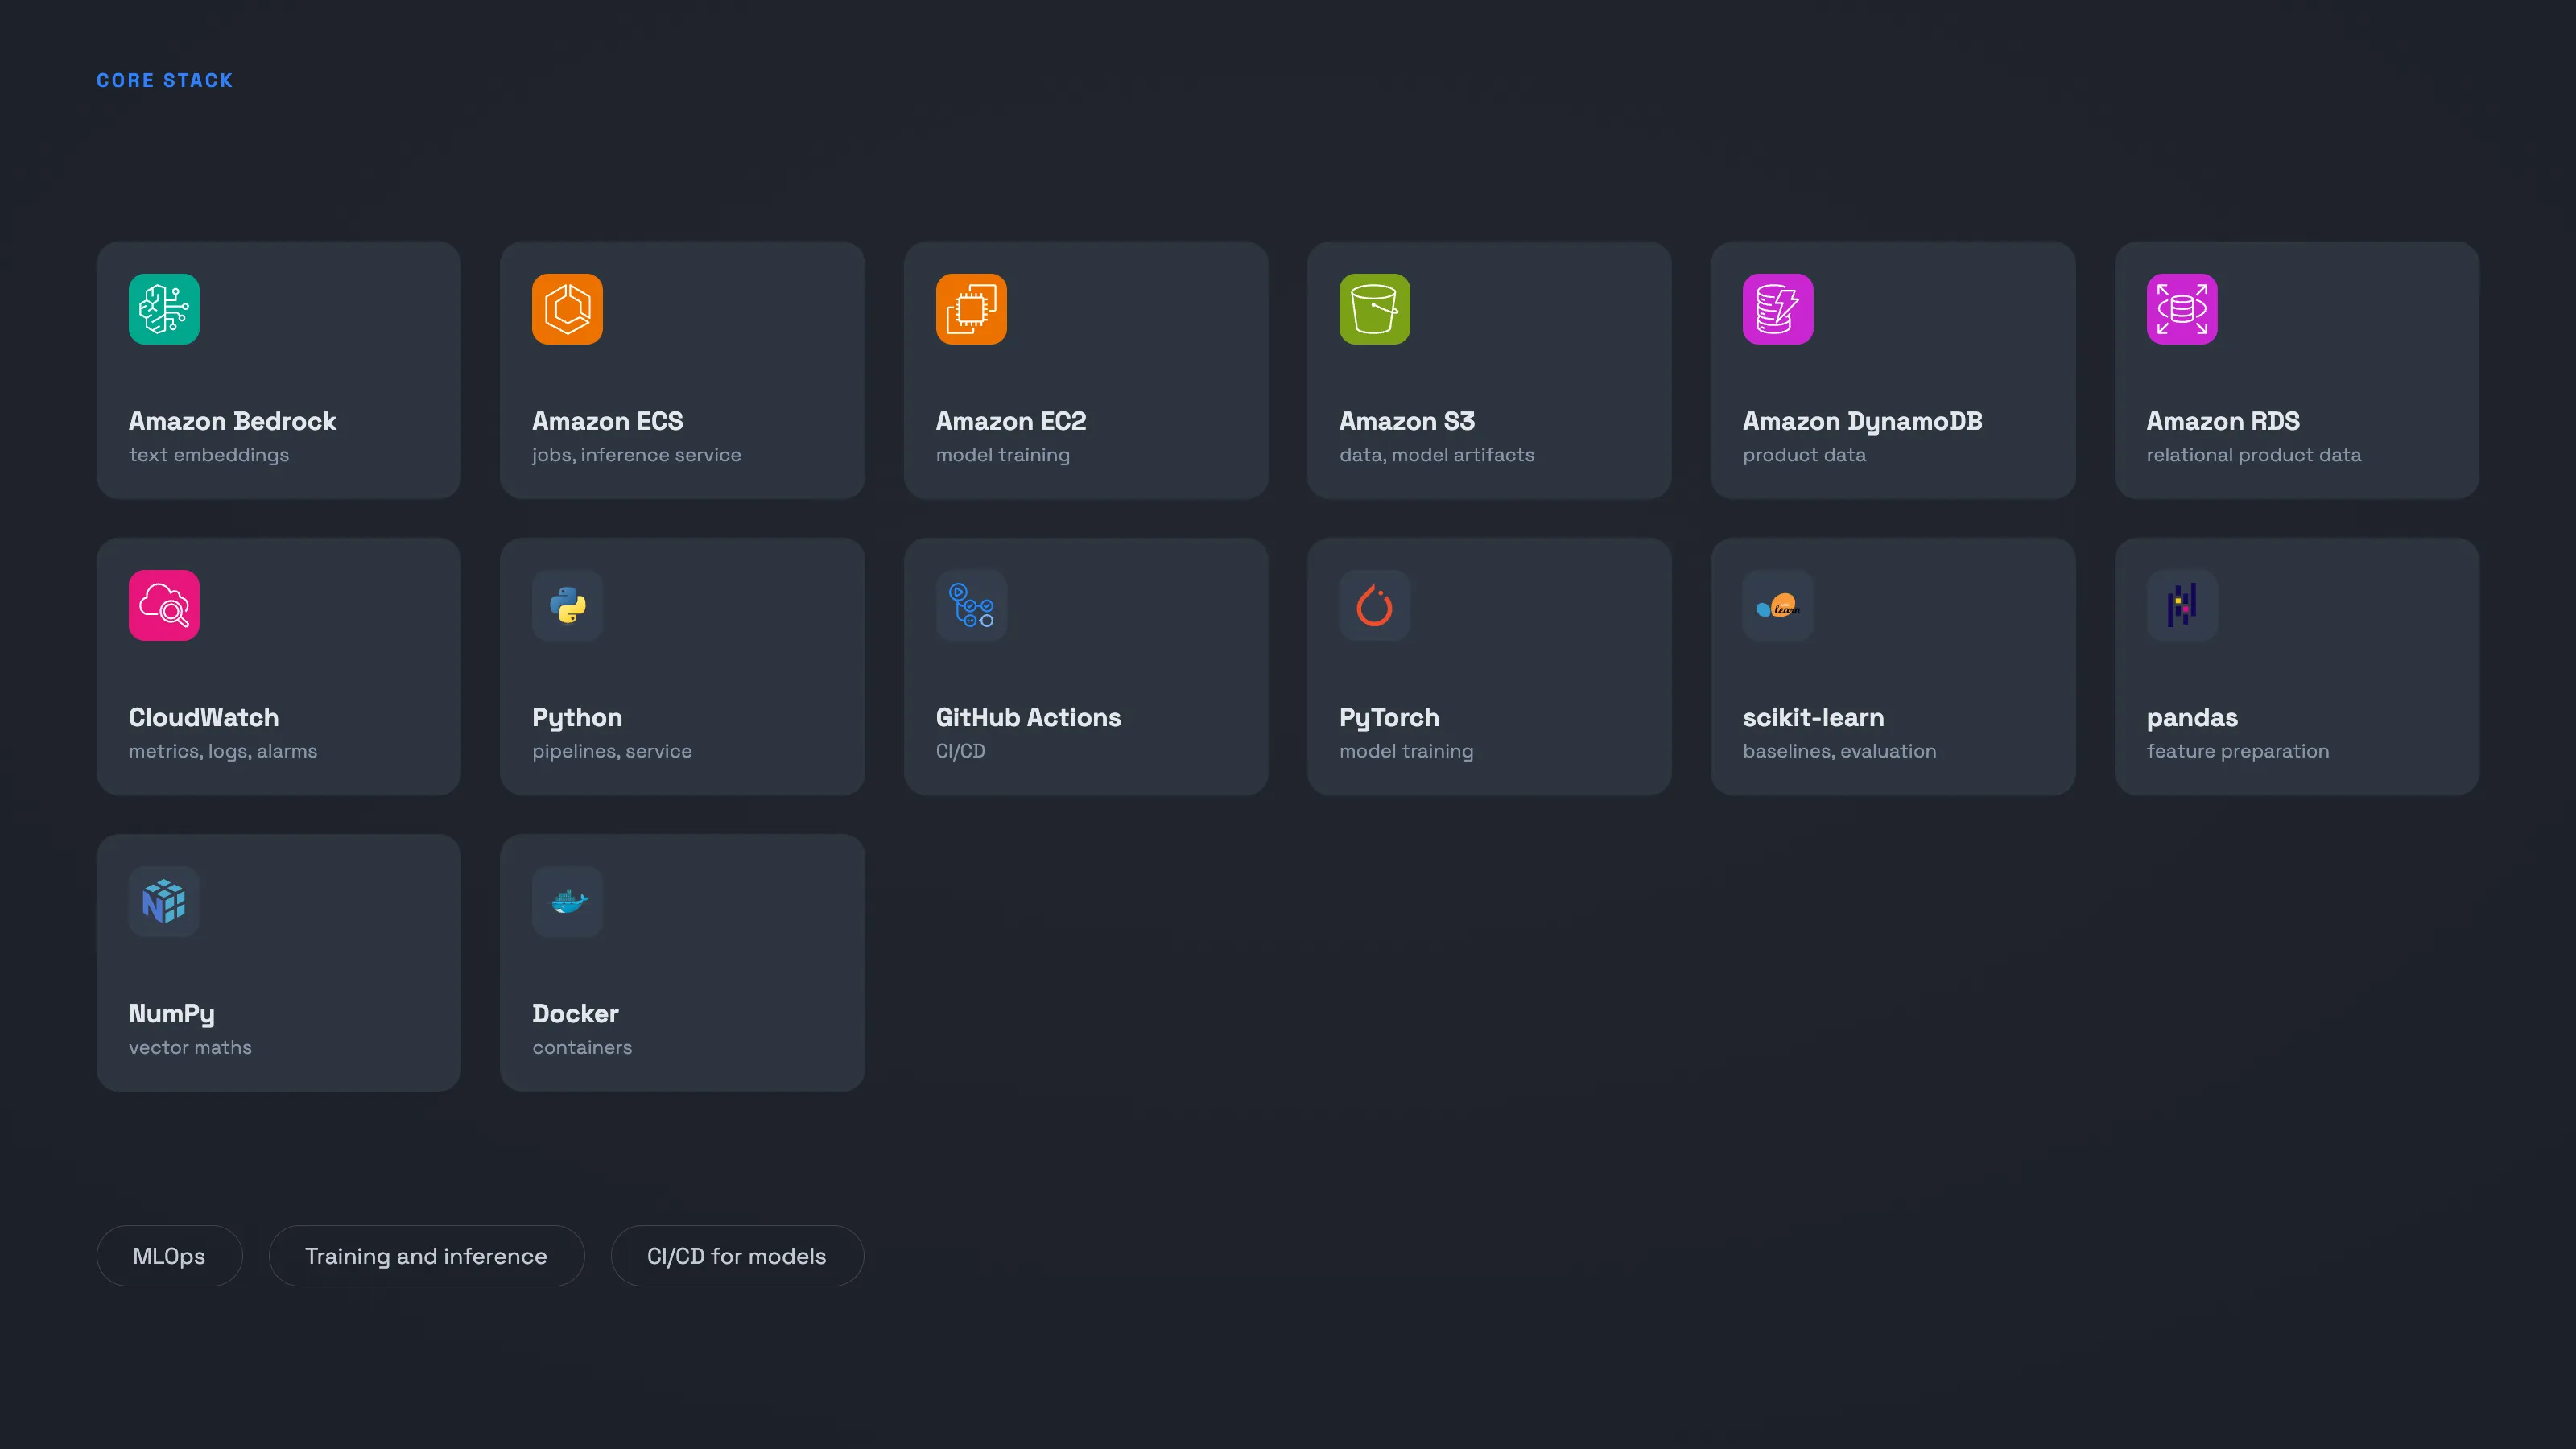
I built the training pipeline. Python jobs read product data from DynamoDB and RDS, prepare features, create text embeddings with Amazon Bedrock and train the model. Data and versioned model artifacts live in S3.
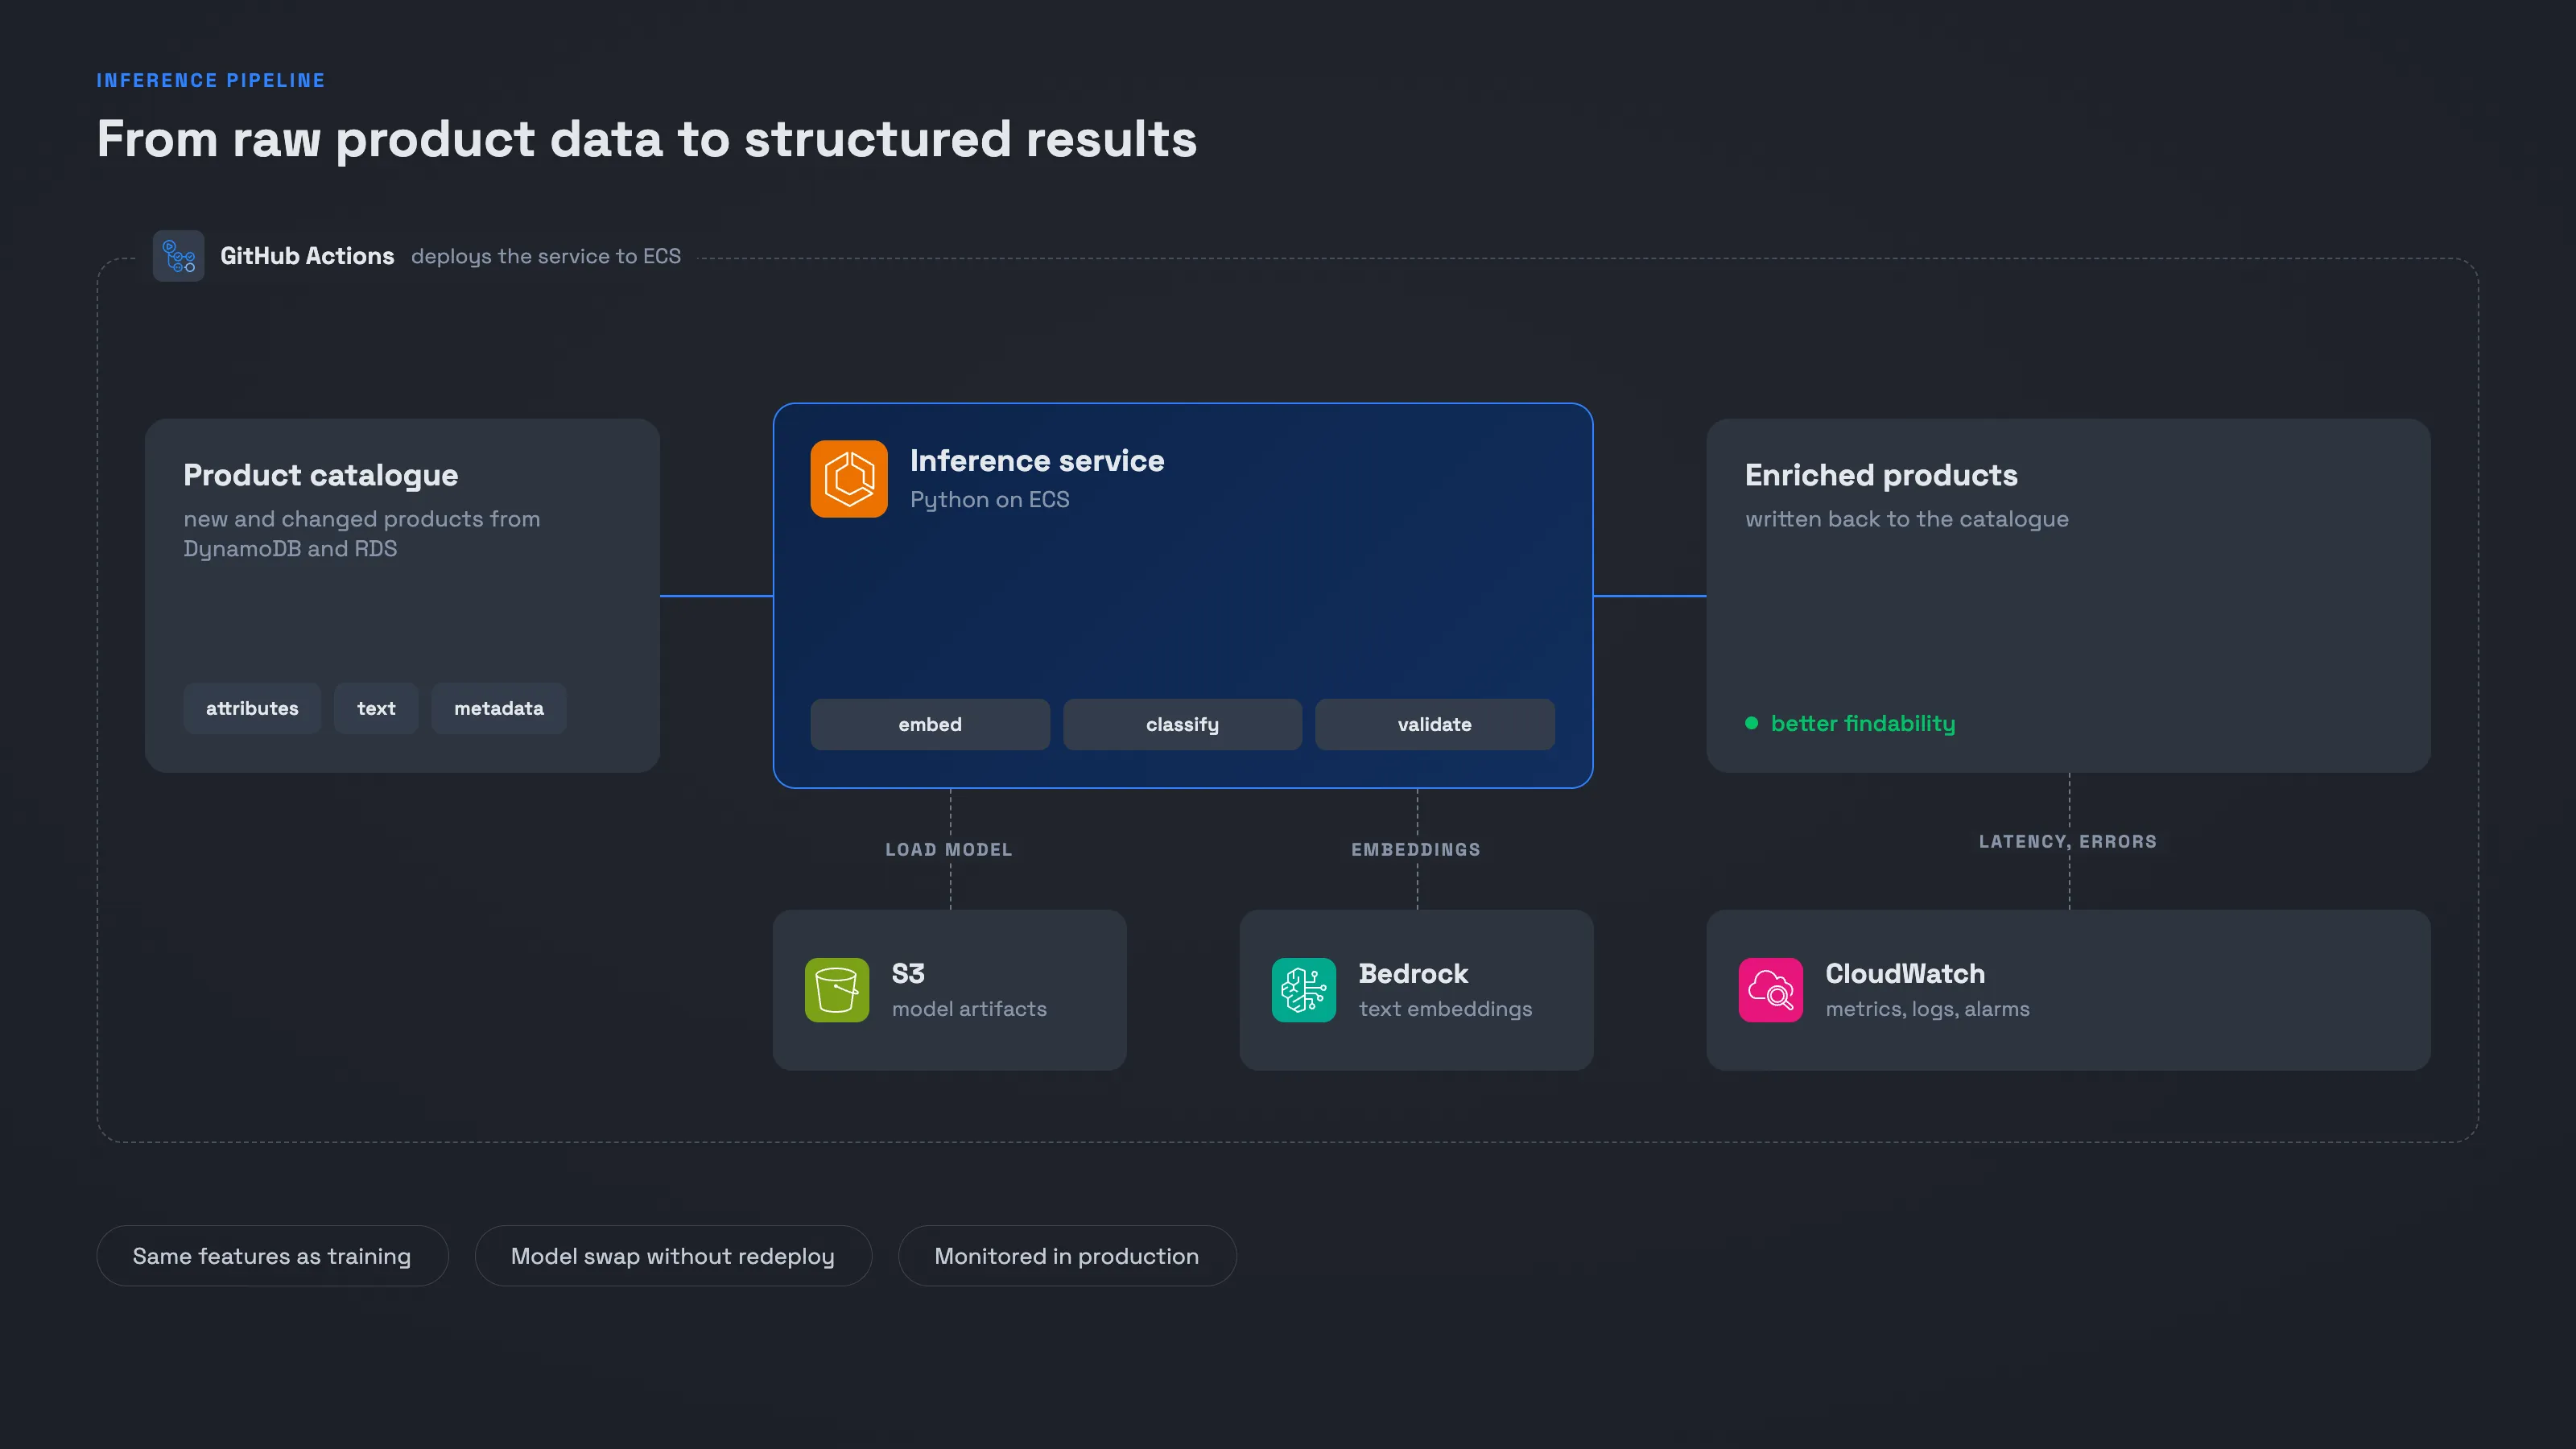
I also built the inference pipeline, a Python service on ECS that classifies new and changed products and writes the results back to the catalogue. It is monitored in CloudWatch and shipped through GitHub CI/CD.
Technology


Other case studies worth a look
Working on something similar?
Tell me what you run today and where it hurts. I will come back with how I would build it, and what I would leave alone.
Discuss your project